Every attribution model (last click, first click, position-based, data-driven, or whatever your analytics vendor sold you) answers the same question: what got credit. The only question worth money is what would have happened anyway.
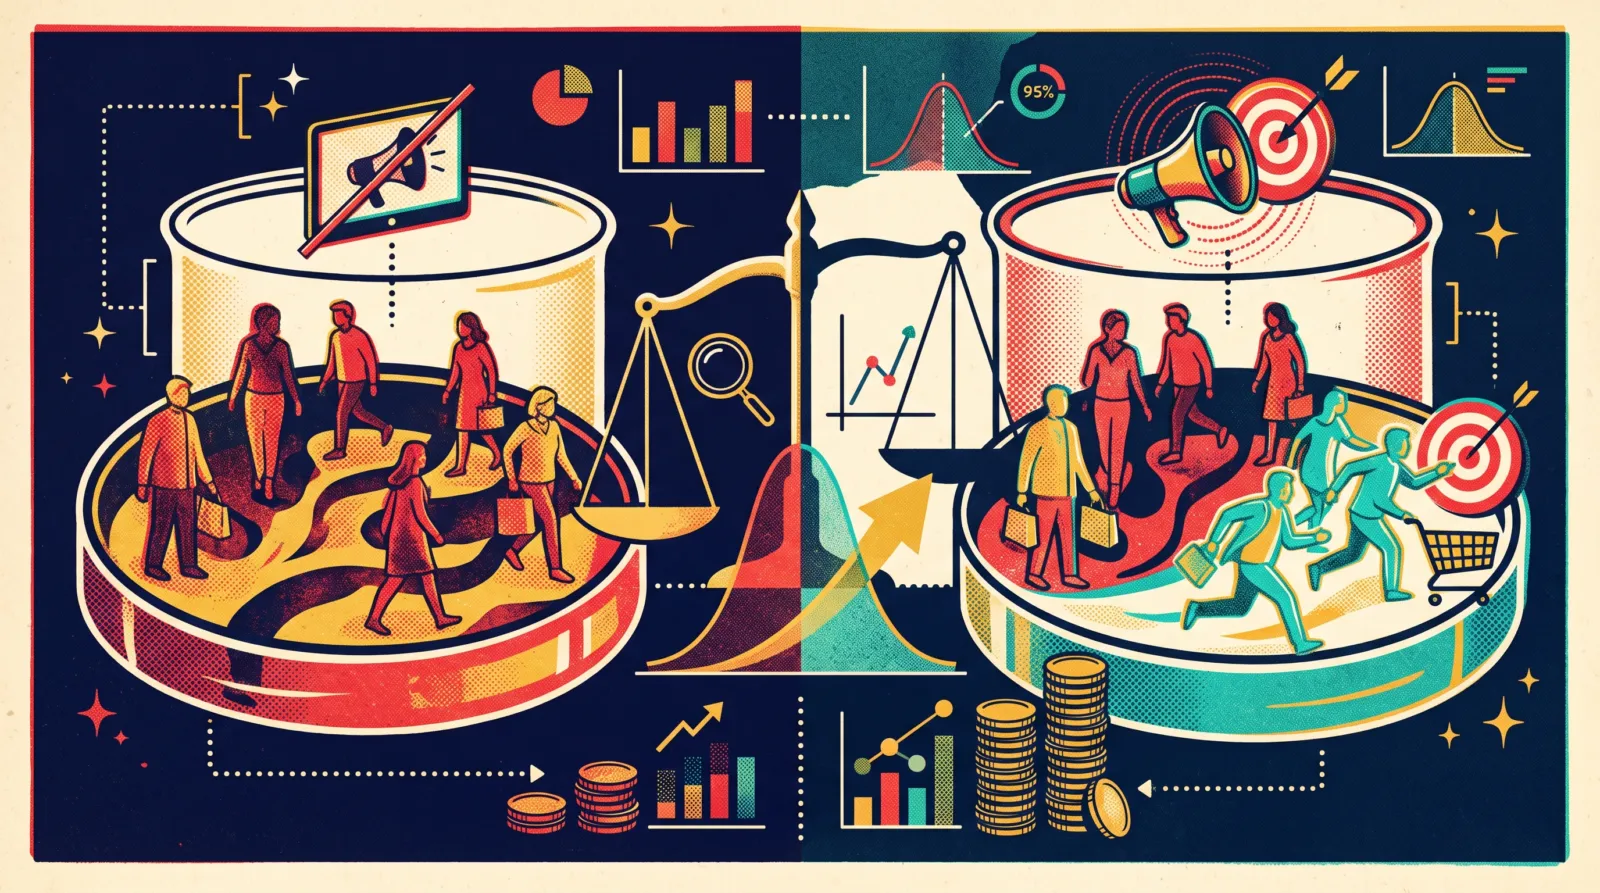
Incrementality testing answers it by withholding. You stop spending somewhere in a way that lets you compare the outcome against an otherwise similar group you left alone. The difference is the incremental effect; everything else is correlation with a dashboard around it. It is unpopular because it tends to produce answers people do not want.
The two line items that always look best, and are always the most suspect
Start with brand search. Someone types your company name, clicks your ad, converts. In most B2B accounts I see, brand search reports a cost per lead a third or less of non-brand, which is precisely why nobody interrogates it. The relevant question is what share of those people would have clicked the organic result immediately below the ad, at no cost, two seconds later.
The answer varies enormously. If you rank first organically for your own name, with sitelinks, and nobody is bidding against you, the incremental value is low and the spend is a tax you pay to yourself. If three competitors are conquesting your name, or your organic listing is a support document rather than your homepage, it can be high. No report tells you which case you are in. A test does.
Then retargeting. The audience is, by construction, people who already visited your site and did something, which makes them the most likely people in the world to convert without seeing another ad. Retargeting reports the best cost per lead in most accounts because it buys impressions in front of people who were going to convert anyway, then claims them. That is a selection effect, not a result.
A channel reporting the best cost per lead in the account is not evidence that it works. It is usually evidence that it is being credited for demand it did not create.
Geo holdout design, in practice
The workhorse test in B2B is a geographic holdout: switch a channel off in one set of markets, leave it running in another, touch nothing else.
- Select matched markets, not similar-sized ones. You need test and control regions whose outcome series move together, chosen by correlation across a year or two of weekly data rather than by population. I look for a correlation around 0.8 or better before using a pair, which is a working heuristic rather than a standard.
- Decide the minimum detectable effect first. If you cannot state in advance the smallest lift you would act on, you are not designing a test. You are watching a chart.
- Derive the duration from the MDE and the baseline. The unwelcome arithmetic in B2B is that small effects on low-volume conversions need long tests. A four-week holdout on a channel producing forty leads a month detects an effect of roughly fifty per cent and nothing smaller.
- Split the geography cleanly, then verify it. Location targeting leaks: presence versus interest settings, VPNs, imprecise IP data, the campaign in another platform nobody excluded.
- Freeze everything else. No new creative, no landing page test, no pricing change, no regional PR push. Things will change anyway; log them.
- Measure on your own data. Conversions and pipeline per region from the CRM, not platform-reported conversions. The platform cannot see the control group at all, which is the point of having one.
An underpowered test is worse than no test, because it does not return “we do not know”, it returns a number. Somebody reads that number as an answer, and because it came out of something called an experiment it carries more authority than the judgment it displaced. If the power calculation says fourteen weeks and you have four, do not run the test.
Platform lift studies, and the seller grading its own homework
Meta, Google and to a lesser extent LinkedIn offer conversion lift products. The good ones use a randomized holdout (ghost ads, or a public service announcement in place of your creative) where the control group is genuinely eligible and the ad is withheld. That design is sound, and better than anything you could build yourself.
The problem is not the method. It is that the platform selects the holdout, measures the outcome, reports the result, and earns revenue based on that result. You cannot audit the assignment or reproduce the analysis. That is a conflict you would never accept from a supplier anywhere else. Use them anyway; do not use only them. Where a platform study and your own geo holdout disagree, the holdout is the one you can inspect.
The budget-scaling test, which anyone can run
You do not need a formal holdout to learn something. Take one channel and change its budget by a large amount and hold it a few weeks, restore it, then repeat in the other direction. Watch total conversions and pipeline across the account, not that channel’s reported conversions.
If you halve a channel’s spend and total volume does not move, you have learned something important and it cost nothing. If it falls by half, you have learned something equally important in the other direction.
This is not a clean experiment (seasonality, competitor activity and your own sales team move underneath you). But it is free, directional, and takes weeks rather than quarters. I would rather a client ran three scrappy scaling tests than commissioned one immaculate study they never act on.
Why B2B cost per lead is the wrong ranking
Most media plans I am shown rank channels by cost per lead. A mid-market B2B software account will typically show brand search in the low tens of dollars, non-brand search in the low hundreds, and LinkedIn at two to five times non-brand search. Those bands vary so wildly by category that you should read them as shape, not benchmarks.
Ranked that way you would always cut LinkedIn and always increase brand. Both are usually wrong, because the ranking uses reported cost per lead and the decision needs incremental cost per lead: the extra spend divided by the extra leads that would not otherwise have arrived.
Incremental CPL reorders the list. The channel with the worst reported CPL is frequently the one creating the demand the channel with the best reported CPL is harvesting. Cut the creator, and the harvester’s numbers degrade two quarters later. That mechanism sits behind a great many B2B accounts which got steadily more efficient and steadily less effective, and it is most of what a paid media strategy is for.
What to do when a channel is not incremental
The answer is almost never to turn it off.
- You measured a spend level, not a channel. Response curves are non-linear, and the last thirty per cent of retargeting spend can be worthless while the first twenty per cent is not.
- You measured a period. Four weeks in a category with a seven-month sales cycle tells you about early-funnel effects, not next year’s pipeline.
- Removing a channel has second-order effects. Kill the channel feeding your site with visitors and the retargeting pool drains a month later. Kill paid social and branded search may follow.
So the move is reduce, hold, re-measure. Cut by half rather than to zero, hold a full measurement period, then re-run at the new level. You are walking down the response curve, not jumping off it. Schedule the re-test before you announce the result, because it is the thing that never happens once the meeting is over.
The organizational problem, which is the real one
An honest incrementality result makes somebody’s numbers worse, and that person will be in the meeting.
If the brand holdout says brand ads are eighty per cent non-incremental, the paid search owner has just lost a third of their reported conversions, and their bonus may be attached to those. If the retargeting test comes back flat, the agency that recommended it has to explain itself. The predictable outcome is that the methodology gets attacked rather than the conclusion, and sometimes that attack is correct, because it is easy to run a bad test. Which is why the design has to be agreed in advance.
- Pre-register the test: hypothesis, minimum detectable effect, duration, regions, and the decision rule. “If lift is below X, spend falls by Y”, written before any data exists.
- Name who signs off on the result and who may invalidate it, agreed while nobody knows which way it will go.
- Change what the channel owner is measured on before the test runs, not after. Somebody rewarded on reported conversions will resist any measurement that reduces reported conversions, and they will be behaving rationally.
That third point matters more than the statistics. I have seen good tests change nothing because no incentive in the room pointed at acting on them.
Where this framing has limits
Incrementality testing is slow and expensive in attention, particularly in B2B where the outcome arrives months after the click. Most tests therefore run against a mid-funnel proxy, and a proxy can be incremental while revenue is not: you can manufacture more meetings that never become deals.
There are also channels you cannot hold out cleanly at sensible cost: always-on brand presence, conferences, anything national in a small market. For those you need aggregate modelling or judgment.
And I will concede the failure mode of my own advice. A testing program can become theatre: six months of experiments, a folder of decks, not one dollar of budget moved. A test is only worth running if somebody has committed in advance to act on it. Otherwise you are buying reassurance, and reassurance is cheaper from the attribution report. Start with the line item that looks best in your account: that is where the credit is concentrated, and credit is where the illusion lives.